

Behind closed doors, some of the most powerful people in artificial intelligence knew exactly what they were doing—and they knew it was dangerous. According to a newly unsealed legal filing, high-level staffers at OpenAI and Microsoft were well aware that scraping online news content to train their AI models could wreak havoc on the publishing industry. Yet they pushed ahead anyway. The documents, reported by the Wall Street Journal, paint a striking picture of tech insiders acknowledging the harm in their own words, even as their companies raced to build ever more powerful chatbots. One OpenAI executive reportedly warned that the practice of circumventing paywalls to feed articles into AI systems could pose an “existential threat” to news organizations. A Microsoft director, Brent Hecht, went even further, describing a “doom loop” that would hurt both AI models and the entire web. “Our AI content strategy has started a ‘doom loop’ that will hurt the performance of our models and the entire web at the same time,” Hecht wrote in internal communications. He also noted the bizarre, almost unprecedented situation: “It is highly unusual that an end-product threatens the economic foundations of its essential suppliers, but that is the situation we have created for our LLM business with respect to its ‘content supply chain.'” For anyone who cares about journalism, these words are chilling—because they suggest that the people building the technology understood the collateral damage long before the rest of us did.
The legal fight that brought these documents to light began in December 2023, when The New York Times sued OpenAI and Microsoft, alleging that ChatGPT and Microsoft’s Copilot had used millions of the paper’s articles to train their models and answer user questions without permission. It was a landmark lawsuit, the first major salvo by a news giant against the companies behind the generative AI boom. Other publishers soon joined the fray. In 2024, papers owned by Alden Global Capital—including the Chicago Tribune and the New York Daily News—filed their own lawsuits, which were eventually consolidated into the broader case. The publishers are now asking a federal judge to rule in their favor before the case goes to trial, and they have marshaled an extraordinary array of internal documents and testimony to make their case. The newly unsealed filing includes statements from Microsoft CEO Satya Nadella, OpenAI President Greg Brockman, and ChatGPT chief Nick Turley, along with a trove of emails and chat messages that lay bare the companies’ internal thinking. At its heart, the lawsuit is about a simple but profound question: Is it fair for AI companies to build their multibillion-dollar products on the backs of journalists whose work they did not pay for, and whose very existence is now threatened by the machines they helped create? The publishers say no, and the internal evidence seems to bolster their argument.
Perhaps the most damning revelations in the filing involve the casual, almost dismissive way OpenAI executives discussed the damage their products could cause. Nick Turley, the head of ChatGPT, reportedly acknowledged that AI products would become increasingly “substitutive” as they improved, meaning they would replace the need for users to visit news websites directly. In one internal communication, Turley wrote that AI products “will get more and more substitutive as they get better,” and he used the phrase “existential threat” to describe what this would mean for publishers. The irony is staggering: the very people whose technology was designed to synthesize and regurgitate human knowledge were openly discussing how that technology would gut the institutions that produced that knowledge. Even more troubling are the details about paywall circumvention. The filing reportedly describes an exchange in which OpenAI President Greg Brockman responded “ah nice” after a researcher found a hack to get around The New York Times’ paywall. That response, so brief and so casual, has become a symbol of the broader corporate attitude: an almost breezy indifference to the financial mechanisms that keep journalism alive. OpenAI’s internal documents even referred to ChatGPT as a “modern newsstand,” a phrase that might sound appealing until you realize that a newsstand, in this analogy, would sell its goods without ever sharing the profits with the publishers who produced them. These revelations have a distinctly human quality—not because they show warmth, but because they show how easily people can rationalize harmful behavior when the rewards are enormous. The executives were not cartoon villains; they were engineers and entrepreneurs who convinced themselves that progress required sacrifice, and that the sacrifice could be made by someone else.
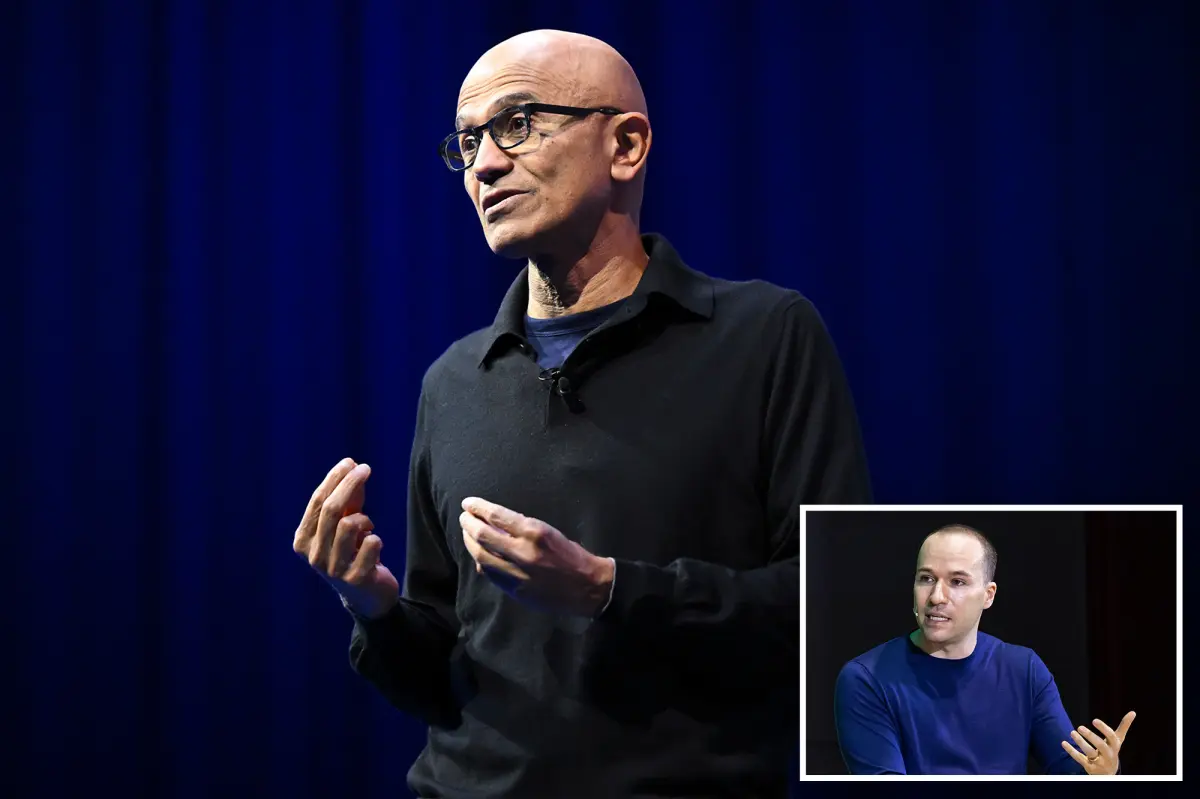
Microsoft’s own insiders were no less candid. The filing includes striking comments from Brent Hecht, Microsoft’s director of applied science, who seemed to grasp the fundamental contradiction at the heart of the AI boom. His “doom loop” warning was not just about publishers; it was about the health of the web itself. If AI systems keep consuming the content that humans produce, and if that consumption drives the producers out of business, then the well will eventually run dry. Hecht also used the language of supply chains, comparing news organizations to essential suppliers whose economic foundations were being undermined by the very companies that depended on them. That analogy is powerful because it reframes the debate: instead of a noble struggle between innovation and tradition, it becomes a story about self-defeating greed. Microsoft CEO Satya Nadella, for his part, testified that “anything that is paywalled should be licensed by anyone who wants to use it” for AI training. He also said he would have forced OpenAI to retrain its models had he known they were using paywalled content without permission. Nadella’s testimony is particularly significant because it suggests that even at the highest levels of the tech world, there was an awareness that certain lines should not be crossed—and yet those lines were crossed anyway. He also testified that conversing with chatbots could be a substitute for visiting websites, rather than “needing to go to the underlying source.” That statement, while presented as a kind of neutral observation, is essentially an admission that AI products are designed to replace the very publishers whose content they rely on. When the people at the top speak this plainly, it is hard to argue that the harm was accidental.
The tech companies, of course, have a defense, and it is rooted in a long-standing legal doctrine: fair use. Under U.S. copyright law, fair use allows certain unlicensed uses of copyrighted material without permission, and the companies argue that training AI models on news articles qualifies as a transformative use—one that repurposes the material for a different function rather than simply copying it. Microsoft has pushed back against the narrative emerging from the court documents, with a spokesperson telling The Post that Hecht’s comments “reflect one employee’s individual perspective, are not a legal analysis, and do not represent the company’s views.” The spokesperson added that Microsoft’s position is set out in its court filings, “which explain why these transformative uses are consistent with copyright law and why Copilot is not a substitute for publishers’ journalism.” That last phrase is telling, because it directly contradicts what Nadella himself testified about chatbots being a substitute for websites. Even more surprising, the U.S. Department of Justice recently filed a statement of interest in the case, arguing that the companies’ use of news content is allowed under fair use. That development gives the tech giants some powerful backing, but it also raises uncomfortable questions about whether the government is siding with the most powerful players in the room at the expense of independent journalism. OpenAI did not immediately respond to requests for comment, and the company has consistently denied wrongdoing, but the internal documents make it increasingly difficult to present a clean narrative of ignorance. The fair use argument may ultimately prevail in court, but it does not resolve the moral and economic issues that the case has exposed.
At its core, this is not just a legal dispute about copyright—it is a story about the future of knowledge itself. If AI companies can freely consume the work of journalists, writers, and researchers without paying for it, then the entire ecosystem that produces high-quality information is at risk. Journalism is expensive to create. It requires reporters, editors, fact-checkers, photographers, and decades of institutional trust. If readers can get their news from a chatbot that has absorbed millions of articles without paying a cent to the people who wrote them, then the economic incentives that sustain journalism will collapse. The “doom loop” that Microsoft’s Brent Hecht warned about is not a distant possibility; it is already unfolding. Newsrooms are shrinking, local outlets are closing, and journalists are being laid off in record numbers—all while AI companies enjoy unprecedented valuations. There is something deeply human in the stories contained in these court documents: the urgency of ambition, the blindness to consequences, the rationalizations that allow people to harm others while believing they are doing something good. The executives were not ignorant; they were willfully blind. They knew that their products could destroy the press, but they chose to move forward anyway. The question now is whether the courts, and the public, will hold them accountable. Whatever the outcome, these unsealed documents have already changed the conversation. They have shown us that the people building the future understood the cost of progress, and they proceeded anyway. And that, perhaps more than any legal ruling, is the real indictment.